In modern Android development, ViewModel has become an indispensable component for managing UI-related data in a lifecycle-conscious manner. One powerful application of ViewModels is sharing data between multiple fragments or activities. This guide provides a deep dive into shared ViewModels, explaining their purpose, implementation, and best practices for creating seamless data sharing in your Android...
State management is one of the most critical aspects of building dynamic and interactive Android applications. With Jetpack Compose, Android’s modern UI toolkit, managing state becomes more intuitive, but it also introduces new paradigms that developers need to understand. In this blog, we’ll explore state management in Jetpack Compose in detail. We’ll break down essential...
In today’s digital world, security and trust are essential, especially when it comes to sensitive information exchanged over the internet. Two foundational technologies that play a critical role in ensuring online security are digital signatures and SSL certificates. If you’re an Android user or developer, understanding these concepts is crucial for protecting your data and...
If you’re diving into the world of Kotlin and exploring data structures, you’ve probably come across linked lists. While arrays and lists are common in Kotlin development, understanding linked lists can open up new levels of flexibility in your coding journey. In this guide, we’ll unravel what linked lists are, why you might need them, and most importantly, how to create and use linked lists in Kotlin.
What is a Linked List?
A Linked List is a data structure consisting of a sequence of elements, called nodes.
Each node has two components:
Data: The value we want to store.
Next: A reference to the next node in the sequence.
Unlike arrays, Linked Lists are dynamic in size, offering efficient insertions and deletions at any position in the list.
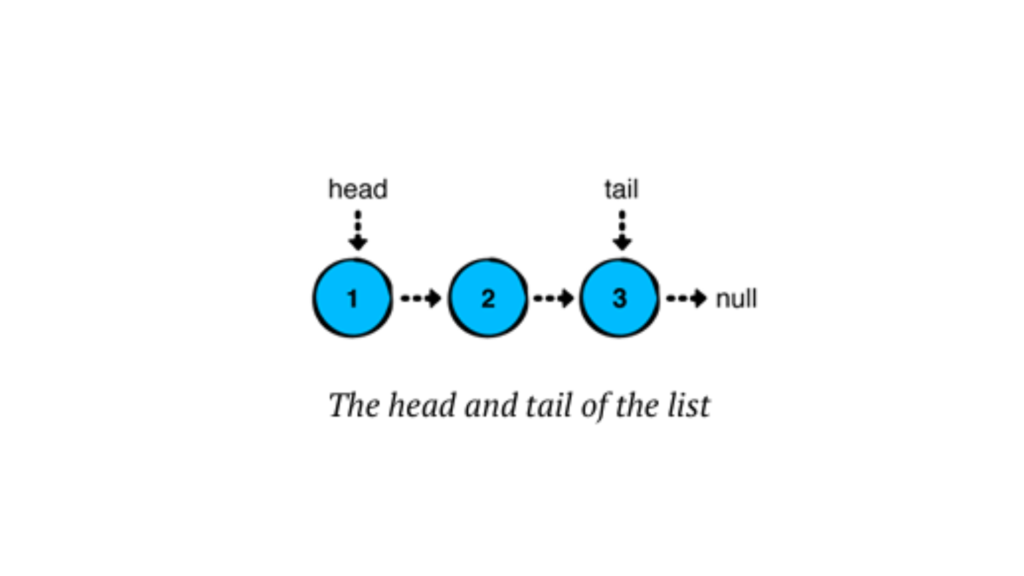
In a linked list, each node stores a value and points to the next node in the chain. The last node in the sequence points to “null,” indicating the end of the list.
Linked lists have several advantages over arrays or ArrayLists in Kotlin:
Quick insertions and removals at the front of the list.
Consistent performance for operations, especially for inserting or removing elements anywhere in the list.
Types of Linked Lists
Singly Linked List — Each node points to the next node in the sequence (we’ll focus on this one).
Doubly Linked List — Each node has a reference to both the next and the previous node.
Circular Linked List — The last node points back to the first node, forming a loop.
Building a Singly Linked List in Kotlin
Kotlin doesn’t offer a built-in linked list class like Java does. But no worries! We’re going to create our own custom Singly Linked List step-by-step. Let’s create a linked list from scratch! We’ll start by defining the Node class and then build a LinkedList class to manage the nodes.
Defining the Node Class
Each node needs to store data and a reference to the next node. Here’s our Node class:
Kotlin
// We define a node of the linked list as a data class, where it holds a value and a reference to the next node.dataclassNode<T>(varvalue: T, var next: Node<T>? = null) {overridefuntoString(): String {returnif (next != null) "$value -> ${next.toString()}"else"$value" }}funmain() {val node1 = Node(value = 1)val node2 = Node(value = 2)val node3 = Node(value = 3) node1.next = node2 node2.next = node3 //here node3 points to null at last, as per our code we only print its valueprintln(node1)}//OUTPUT1->2->3
Here, we defined a generic Node class for a linked list in Kotlin. Each Node holds a value of any type (T) and a reference to the next Node, which can be null. The toString() method provides a custom string representation for the node, recursively displaying the value of the node followed by the values of subsequent nodes, separated by ->. If the node is the last in the list, it simply shows its value.
Have you observed how we constructed the list above? We essentially created a chain of nodes by linking their ‘next’ references. However, building lists in this manner becomes impractical as the list grows larger. To address this, we can use a LinkedList, which simplifies managing the nodes and makes the list easier to work with. Let’s explore how we can implement this in Kotlin.
Creating the LinkedList Class
Let’s create our LinkedList class and add core functionalities like adding nodes and displaying the list.
Basically, a linked list has a ‘head’ (the first node) and a ‘tail’ (the last node). In a singly linked list, we usually only deal with the head node, although the tail node can also be relevant, especially when adding elements at the end. The tail node becomes more important in doubly linked lists or circular linked lists, where it supports bidirectional traversal or maintains circular references. However, here, we will use both nodes in a singly linked list.
Kotlin
classLinkedList<T> {privatevar head: Node<T>? = nullprivatevar tail: Node<T>? = nullprivatevar size = 0// Method to check if the list is emptyfunisEmpty(): Boolean = size == 0// to print nodes in linkedlistoverridefuntoString(): String {if (isEmpty()) {return"Empty list" } else {return head.toString() } }}
Here, a linked list has a ‘head’ (the first node) and a ‘tail’ (the last node). We’ll also store the list’s size in a ‘size’ property.
Now, to use this linked list, we need to store or add some values to it. Otherwise, we’d only be using an empty list. There are three major operations for adding values to a linked list, and we’ll explore each one in more details in the next blog. First, let’s see how to add a new value (or node) to the linked list and then print the result.
Kotlin
// Method to add a new node at the beginningfunaddFirst(data: T) {val newNode = Node(data) newNode.next = head head = newNode size++}
Here, we first create a new node with the passed value. Then, the new node’s next points to the head, and finally, we update the head to point to the newly created node. The same process is repeated whenever we add a new value.
Note: Whenever a new value is added, the list size increases. Therefore, we need to increment the size accordingly.
Now, let’s look at the complete code.
Kotlin
classLinkedList<T> {privatevar head: Node<T>? = nullprivatevar tail: Node<T>? = nullprivatevar size = 0// Method to check if the list is emptyfunisEmpty(): Boolean = size == 0// to print nodes in linkedlistoverridefuntoString(): String {if (isEmpty()) {return"Empty list" } else {return head.toString() } }// Method to add a new node at the beginningfunaddFirst(data: T) {val newNode = Node(data) newNode.next = head head = newNode size++ }}
Using the Linked List in Kotlin
Let’s put our linked list to the test! Here’s how we can use the LinkedList class:
Kotlin
funmain() {val myList = LinkedList<String>()println("Is the list empty? ${myList.isEmpty()}") myList.addFirst("Kotlin") myList.addFirst("Hello")println(myList) // Output: Hello -> Kotlin -> nullprintln("Is the list empty? ${myList.isEmpty()}")}
Output
Kotlin
Is the list empty? trueHello -> KotlinIs the list empty? false
Conclusion
We’ve explored the key insertion operations in linked lists, along with the foundational concepts and structure that make them an essential part of data management. Understanding these operations provides a solid base for working with linked lists in various scenarios.
Linked lists might seem daunting, but with a bit of practice, you’ll be using them like a pro.
With Android’s continuous evolution, power management has become increasingly fine-tuned. Starting from Android 9 (API level 28), Android introduced App Standby Buckets, a dynamic classification system that governs how apps can access system resources based on their usage patterns.
These buckets are essential for developers who rely on background jobs, alarms, or network access to power their app’s core functionality.
In this post, we’ll explore what these buckets are, how they limit your app’s capabilities, and how you can optimize your app to function efficiently within these boundaries.
What Are App Standby Buckets?
App Standby Buckets categorize apps based on how frequently they are used. Android uses a combination of machine learning and user behavior analysis to dynamically assign apps to a bucket.
The buckets help Android prioritize system and battery resources without degrading the user experience.
Here are the five main buckets:
Active — App is currently in use or was used very recently.
Working Set — App used often, possibly running in the background.
Frequent — App used regularly but not daily.
Rare — App used infrequently.
Restricted — App is misbehaving or user has manually restricted it.
Resource Limits by Standby Bucket
Each bucket determines how much access an app has to jobs, alarms, and network activity. Below is a breakdown of the execution time windows for each resource type:
Active
Regular Jobs: Up to 20 minutes in a rolling 60-minute period
Expedited Jobs: Up to 30 minutes in a rolling 24-hour period
Alarms: No execution limits
Network Access: Unrestricted
Note (Android 16+): Prior to Android 16, apps in the Active bucket had no job execution limit.
Working Set
Regular Jobs: Up to 10 minutes in a rolling 4-hour period
Expedited Jobs: Up to 15 minutes in a rolling 24-hour period
Alarms: Limited to 10 per hour
Network Access: Unrestricted
Frequent
Regular Jobs: Up to 10 minutes in a rolling 12-hour period
Expedited Jobs: Up to 10 minutes in a rolling 24-hour period
Alarms: Limited to 2 per hour
Network Access: Unrestricted
Rare
Regular Jobs: Up to 10 minutes in a rolling 24-hour period
Expedited Jobs: Up to 10 minutes in a rolling 24-hour period
Alarms: Limited to 1 per hour
Network Access: Disabled
Restricted
Regular Jobs: Once per day for up to 10 minutes
Expedited Jobs: Up to 5 minutes in a rolling 24-hour period
Alarms: One per day (exact or inexact)
Network Access: Disabled
Regular vs. Expedited Jobs
Android distinguishes between two types of scheduled jobs:
Regular Jobs: Standard background tasks scheduled via JobScheduler or WorkManager.
Expedited Jobs: Urgent, high-priority jobs using setExpedited(true) or expedited workers in WorkManager.
Expedited jobs have separate quotas from regular jobs. Once those quotas are exhausted, they may still run under the regular job limits.
Best Practice: Use expedited jobs only for urgent tasks. For everything else, rely on regular job scheduling.
Alarm Limits
Starting with Android 12, alarm limits have tightened:
Apps in Working Set or below are subject to hourly or daily caps.
Apps in the Restricted bucket can schedule only one alarm per day (exact or inexact).
If your app depends on alarms, consider alternatives like JobScheduler or WorkManager, especially for non-critical tasks.
Network Access Limitations
Apps in the Rare and Restricted buckets cannot access the network unless they are running in the foreground.
This has big implications for features like:
Background syncing
Data uploads
Real-time updates
Make sure to test network-reliant tasks across all bucket conditions.
Android 13+ Update: FCM Quota Change
As of Android 13, the number of high-priority Firebase Cloud Messaging (FCM) messages an app can receive is no longer tied to the standby bucket.
This change benefits apps that rely on push messages (like messaging or ride-sharing apps), ensuring more consistent delivery.
Developer Tips for Bucket Optimization
Track App Usage Use UsageStatsManager to monitor your app’s current bucket status.
Leverage WorkManager It automatically handles job fallback between expedited and regular quotas.
Respect Background Limits Overusing background resources can land your app in the Restricted bucket.
Batch and Defer Tasks Reduce battery drain and stay in higher buckets longer by batching non-critical jobs.
Test Across Buckets Simulate different standby buckets with this ADB command:
App Standby Buckets are a key piece of Android’s power management strategy. By tailoring your background behavior to each bucket’s constraints, you not only improve performance and battery life but also ensure a smoother user experience.
Understanding how these limits work — and respecting them — helps you build apps that are efficient, resilient, and Play Store compliant.
FAQs
Q: Can I manually move my app to a different bucket? A: No. The system dynamically assigns apps based on usage. You can only simulate bucket placement during testing.
Q: Do background restrictions help battery life? A: Yes, but they can also restrict your app’s background capabilities. Design wisely.
Q: How do I test alarms or jobs under low buckets like Rare or Restricted? A: Use ADB to simulate conditions, monitor behavior, and fine-tune fallback strategies.
Encryption is powerful, but if you don’t manage keys securely or follow best practices, your data might still be at risk. Here’s what you should know when working with encryption in Kotlin, especially for Android apps. Why Is Key Management So Important? Think of encryption keys like the keys to your house. If someone steals...
If you’re getting started with Android Automotive OS (AAOS), you’ll quickly run into something called Car Service in AOSP. It’s one of those essential components that makes Android work inside a car — not on your phone, but actually on the car’s infotainment system. In this guide, we’ll break down Car Service in AOSP step-by-step, explain how...
Software isn’t just about solving problems — it’s about making solutions expressive and readable. One powerful way to do this is by building Internal DSLs (Domain-Specific Languages). If you’ve ever wished your code could read more like English (or your team’s own domain language), then an internal DSL might be the tool you’re looking for. What Are...
If you’re working in IT or managing virtual environments, you’ve probably come across the term VHDX. But what exactly is it, why does it matter, and how can you use it effectively? In this post, we’ll break down VHDX in virtualization in simple way, walk through its benefits, explain how it works internally, and even cover some practical examples with code snippets. By the end, you’ll know exactly how VHDX fits into your virtualization strategy.
What Is VHDX?
VHDX stands for Virtual Hard Disk v2. It’s a disk image file format introduced with Windows Server 2012 as an upgrade to the older VHD (Virtual Hard Disk) format.
Think of VHDX as a virtual hard drive — just like a physical disk in your computer, but stored as a single file on your host system. Inside it, you can install operating systems, store data, and run applications — all within a virtual machine (VM).
The key difference: VHDX supports modern workloads. It’s more resilient, can handle much larger disk sizes, and protects against corruption better than its predecessor.
Why VHDX Matters in Virtualization
Virtualization thrives on efficiency and flexibility. Here’s why VHDX in virtualization is so valuable:
Bigger capacity: Supports up to 64 TB compared to VHD’s 2 TB limit.
Improved performance: Handles large block sizes better, ideal for workloads like databases.
Resilience: Includes logging to protect against data corruption during crashes or power failures.
Alignment with modern storage: Optimized for large sector disks (4 KB).
Dynamic resizing: VHDX files can grow or shrink without downtime.
For IT pros, this means fewer limits, more stability, and better handling of enterprise-scale virtual machines.
VHD vs. VHDX: Quick Comparison
If you’re setting up new virtual environments, VHDX should be your default choice unless you need compatibility with legacy systems.
How VHDX Works in Virtualization
When you create a new VM in Hyper-V or another virtualization platform, you’re usually asked to attach a virtual hard disk. This disk is stored as a .vhdx file. The guest OS inside your VM sees it as a standard hard drive.
Under the hood, the host system manages all the reads/writes to the .vhdx file and ensures that data is written correctly—even during unexpected events like power loss.
Here’s the important part: the VM only sees logical space. The host decides whether to reserve that space upfront or let the file grow over time. This brings us to the two disk types you can choose: fixed-size and dynamic.
Fixed vs. Dynamic VHDX
Fixed-size VHDX
Allocates the full size immediately. If you create a 200 GB fixed disk, the host’s storage instantly reserves 200 GB.
Performance is predictable and slightly faster.
Best for mission-critical workloads like databases.
Dynamic VHDX
Starts small and grows as data is added. A 200 GB dynamic disk might only consume 10 GB on the host if that’s all the VM is using.
More space-efficient and flexible.
Best for general-purpose or test/dev environments.
This flexibility is why logical allocation is common. If every VM grabbed its full allocation upfront, host storage would be consumed very quickly, even if most VMs weren’t using their full disks.
Why Not Just Use Physical Allocation Always?
It’s a fair question: why let VMs think they have more space than the host physically has?
Efficiency: Most VMs never use their full allocated size. Logical allocation avoids wasting host storage.
Scalability: In enterprise environments with hundreds of VMs, fixed pre-allocation would demand massive upfront storage. Dynamic allocation enables faster scaling.
Performance Trade-off: Fixed disks give the best speed and predictability, but dynamic disks offer flexibility. IT admins choose based on workload needs.
Abstraction: Virtualization is about creating an illusion. The VM doesn’t need to know the true storage situation — it just needs a disk to run.
Note: Over-provisioning (promising more logical space than you physically have) can be risky. If all VMs try to use their full allocation at once, the host can run out of storage. That’s why monitoring is essential.
A Quick Analogy
Think of your physical disk as an airplane with 200 seats.
If you create fixed disks, it’s like selling only 200 tickets — safe, predictable.
If you use dynamic disks, it’s like selling 220 tickets, betting not everyone will show up.
Usually, it works. But if everyone does show up (all VMs demand full storage), you’ll have a problem unless you planned ahead.
Creating a VHDX File
You can create and manage VHDX files using PowerShell, which makes automation easy for IT admins.
-Path: Location where the .vhdx file will be stored.
-SizeBytes: Maximum size (50GB in this case).
-Dynamic: The file grows as data is added, instead of consuming the full 50GB immediately.
Add-VMHardDiskDrive: Attaches the new disk to the VM named TestVM.
This simple script saves time compared to clicking through the Hyper-V Manager GUI.
Best Practices for Using VHDX in Virtualization
Pick the right type: Fixed for performance-critical workloads, dynamic for flexibility.
Back up regularly: VHDX is resilient, but backups are still mandatory.
Watch over-provisioning: Dynamic disks can silently grow and consume host storage.
Convert old VHDs: Use PowerShell’s Convert-VHD to move from legacy VHD to VHDX.
Use checkpoints wisely: Helpful for testing, but they can bloat disk usage.
Conclusion
VHDX in virtualization is the modern standard for virtual hard disks. It offers scalability, resilience, and efficiency that older formats can’t match. For IT professionals managing enterprise workloads, switching to VHDX ensures that your virtual machines are future-ready.
Key takeaway: VHDX doesn’t magically create storage. It allocates logical space to give flexibility and efficiency, while physical space is consumed only as needed. This balance is what makes virtualization powerful — but it also requires careful monitoring and planning.
When we talk about password security, the conversation usually goes straight to hashing algorithms — things like SHA-256, bcrypt, or Argon2. But there are two lesser-known players that can make or break your defenses: salts and pepper. Think of them as seasoning for your password hashes — not for flavor, but for security. Why Password Hashing Alone Isn’t Enough Hashing is...