When working with lists in Kotlin, a common task is to find the two smallest numbers. Whether you’re solving coding challenges, optimizing algorithms, or simply manipulating data, knowing how to efficiently extract the smallest elements is useful. In this blog, we’ll explore different ways to find the two smallest numbers in a Kotlin list. We’ll...
When analyzing algorithms, time complexity plays a crucial role in determining their efficiency. Two common complexities encountered in sorting, searching, and data structure operations are O(n) (linear time) and O(n log n) (linearithmic time). But which one is better? In this blog, we will explore both complexities in detail, understand their significance, and compare them...
Generics in Kotlin can seem complex at first, but once you understand their power, they make your code more flexible and reusable. In this blog, we’ll break down generics in a simple way, focusing on generic functions and properties and best practices.
What Are Generics in Kotlin?
Generics allow you to write code that works with different data types without sacrificing type safety. Instead of specifying an exact type, you define a placeholder type that gets replaced with a real type at runtime.
For example, consider a function that prints any type of element. Instead of writing separate functions for Int, String, and other types, you can use generics to make it work for any type.
A generic function uses a type parameter to make it more flexible. The type parameter is placed inside angle brackets (<>) before the function’s parameter list.
A Simple Generic Function
Kotlin
fun <T> printItem(item: T) {println(item)}funmain() {printItem(42) // Works with IntprintItem("Hello") // Works with StringprintItem(3.14) // Works with Double}
<T> is the type parameter.
T is used as the parameter type inside the function.
The function can now accept any type, making it more reusable.
Kotlin’s generics allow for reusable and type-safe code. By understanding generic functions and properties, you can write cleaner and more efficient Kotlin programs. Follow best practices, use it wisely, and keep your code readable.
Now that you have a solid grasp, try using generic functions and properties in your own Kotlin projects!
Kotlin is a powerful language that puts a strong emphasis on null safety. However, when working with generics, it’s easy to accidentally allow nullability, even when you don’t intend to. If you’re wondering how to enforce non-null type parameters properly, this guide will walk you through the right approach.
Why Enforcing Non-Null Type Parameters Matters
Kotlin’s type system prevents null pointer exceptions by distinguishing between nullable and non-nullable types. However, generics (T) are nullable by default, which can lead to unintended issues if not handled correctly.
For example, consider the following generic class:
Kotlin
classContainer<T>(valvalue: T)
Here, T can be any type—including nullable ones like String?. This means that Container<String?> is a valid type, even if you don’t want to allow null values.
Making type parameters non-null
In Kotlin, when you declare a generic class or function, you can substitute any type argument, including nullable types, for its type parameters. By default, a type parameter without an upper bound specified will have the upper bound of Any? which means it can accept both nullable and non-nullable types.
Let’s take an example to understand this. Consider the Processor class defined as follows:
Kotlin
classProcessor<T> {funprocess(value: T) {value?.hashCode() // value” is nullable, so you have to use a safe call }}
In the process function of this class, the parameter value is nullable, even though T itself is not marked with a question mark. This is because specific instantiations of the Processor class can use nullable types for T. For example, you can create an instance of Processor<String?> which allows nullable strings as its type argument:
Kotlin
val nullableStringProcessor = Processor<String?>() // String?, which is a nullable type, is substituted for TnullableStringProcessor.process(null) // This code compiles fine, having “null” as the “value” argument
If you want to ensure that only non-null types can be substituted for the type parameter, you can specify a constraint or an upper bound. If the only restriction you have is nullability, you can use Any as the upper bound instead of the default Any?. Here’s an example:
Kotlin
classProcessor<T : Any> { // Specifying a non-“null” upper boundfunprocess(value: T) {value.hashCode() // “value” of type T is now non-“null” }}
In this case, the <T : Any> constraint ensures that the type T will always be a non-nullable type. If you try to use a nullable type as the type argument, like Processor<String?>(), the compiler will produce an error. The reason is that String? is not a subtype of Any (it’s a subtype of Any?, which is a less specific type):
Kotlin
val nullableStringProcessor = Processor<String?>()// Error: Type argument is not within its bounds: should be subtype of 'Any'
It’s worth noting that you can make a type parameter non-null by specifying any non-null type as an upper bound, not only Any. This allows you to enforce stricter constraints based on your specific needs.
The Wrong Way: Using T : Any?
Some developers mistakenly try to restrict T by writing:
Kotlin
classContainer<T : Any?>(valvalue: T)
However, this does not enforce non-nullability. The bound Any? explicitly allows both Any (non-null) and null. This approach is unnecessary since T is already nullable by default.
The Right Way: Enforcing Non-Null Type Parameters
To ensure that a type parameter is always non-null, you should use an upper bound of Any instead:
Kotlin
classContainer<T : Any>(valvalue: T)
Why This Works
The constraint T : Any ensures that T must be a non-nullable type.
Container<String?>will not compile, preventing unintended nullability.
You still maintain type safety and avoid potential null pointer exceptions.
These patterns ensure that all implementations respect non-nullability.
Conclusion
Making type parameters non-null in Kotlin is essential for writing safer, more predictable code. Instead of leaving T nullable or mistakenly using T : Any?, enforce non-nullability using T : Any. This simple yet powerful technique helps prevent unexpected null values while maintaining the flexibility of generics.
By applying this Kotlin tip, you can improve your code’s safety and avoid common pitfalls related to nullability.
Reification is a powerful concept in Kotlin that allows us to retain generic type information at runtime. However, it comes with a significant limitation: it only works for inline functions. But why is that the case? Let’s explore the reasons behind this restriction and understand how reification truly works. Understanding Reification In most JVM-based languages,...
Kotlin has gained immense popularity for its modern and expressive syntax, making Android development and general programming more efficient. One of its unique features is the companion object, which allows defining static-like members within a class. If you’re a beginner looking to understand Kotlin companion objects, this guide will take you through every essential detail.
What is a Kotlin Companion Object?
In Kotlin, unlike Java, there are no static methods. Instead, Kotlin provides a way to achieve similar functionality using companion objects. A Kotlin Companion Object is an object associated with a class that allows you to access its properties and methods without creating an instance of the class.
Key Characteristics:
A companion object is defined inside a class using the companion keyword.
It behaves like a singleton, meaning there is only one instance of it per class.
You can access its properties and methods using the class name, just like static members in Java.
How to Declare a Companion Object
Declaring a companion object in Kotlin is simple. Use the companion object keyword inside a class.
Kotlin
classMyClass {companionobject {funsayHello() {println("Hello from Companion Object!") } }}funmain() { MyClass.sayHello() // Calling the function without creating an instance}
Here,
The companion object inside MyClass defines a function sayHello().
MyClass.sayHello() is called directly, without creating an instance.
This behavior is similar to Java’s static methods but follows Kotlin’s object-oriented approach.
Adding Properties in a Companion Object
You can also define properties inside a companion object.
The companion object implements the Logger interface.
Now, Service.log("Service started") logs a message without an instance.
Conclusion
Kotlin companion objects provide a powerful way to create static-like functionality while keeping an object-oriented structure. They enable defining functions, properties, factory methods, and interface implementations within a class, making code more readable and maintainable.
Now that you have a clear understanding, start using companion objects in your Kotlin projects and take advantage of their benefits..!
Generics in Kotlin add flexibility and type safety, but sometimes we don’t need to specify a type. This is where star projection (*) comes in. In this blog, we’ll explore star projection in Kotlin, its use cases, and practical examples to help you understand how and when to use it. Understanding Star Projection in Kotlin In...
Kotlin coroutines are a powerful feature that simplify asynchronous programming. They allow developers to write asynchronous code in a sequential manner, making it easier to read and maintain. At the heart of coroutines are coroutine builders, specifically launch and async. These builders define how coroutines are started and managed. In this blog, we’ll dive deep...
Kotlin is a powerful programming language that simplifies development while maintaining strong type safety. One of the essential concepts in Kotlin is variance, which helps us understand how generics and subtyping work. If you’ve ever been confused by out, in, or *, and how generics behave in Kotlin, this guide is for you. Variance: generics...
Kotlin is well known for its concise syntax, expressive features, and seamless support for functional programming. One of its powerful yet often misunderstood features is inline functions. If you’ve ever worked with higher-order functions in Kotlin, you’ve probably encountered situations where performance becomes a concern due to lambda expressions. This is where inline functions in Kotlin come to the rescue!
In this guide, we’ll break down everything you need to know about inline functions, why they exist, how they work and improve performance, and when (or when not) to use them. Whether you’re a beginner or an experienced developer looking for a refresher, this post will help you grasp inline functions in Kotlin with clear explanations and practical examples.
What Are Inline Functions in Kotlin?
Before diving into the details, let’s start with a simple definition.
In Kotlin, an inline function is a function whose body is copied (or “inlined”) at every place it’s called during compilation. This eliminates the overhead of function calls, making the code more efficient, especially when working with lambda functions.
In this case, the function greet() is marked as inline, which means that when greet("amol") is called, the compiler replaces it with:
Kotlin
println("Hello, amol!")
This eliminates the function call and directly places the function body in the main() function, improving efficiency.
Why Were Inline Functions Introduced in Kotlin?
In Kotlin, inline functions can help remove the overhead associated with lambdas and improve performance. When you use a lambda expression, it is typically compiled into an anonymous class. This means that each time you use a lambda, an additional class is created. Moreover, if the lambda captures variables, a new object is created for each invocation. As a result, using Lambdas can introduce runtime overhead and make the implementation less efficient compared to directly executing the code.
To mitigate this performance impact, Kotlin provides the inline modifier for functions. When you mark a function with inline, the compiler replaces every call to that function with the actual code implementation, instead of generating a function call. This way, the overhead of creating additional classes and objects is avoided.
Let’s see a simple example to illustrate this:
Kotlin
inlinefunmultiply(a: Int, b: Int): Int {return a * b}funmain() {val result = multiply(2, 3)println(result)}
In this example, the multiply function is marked as inline. When you call multiply(2, 3), the compiler replaces the function call with the actual code of the multiply function:
Kotlin
funmain() {val result = 2 * 3// only for illustrating purposes, later we will see how it actually works println(result)}
This allows the code to execute the multiplication directly without the overhead of a function call.
Let’s see one more example to illustrate this:
Kotlin
inlinefunperformOperation(a: Int, b: Int, operation: (Int, Int) -> Int): Int {returnoperation(a, b)}funmain() {val result = performOperation(5, 3) { x, y -> x + y }println(result)}
In this example, the performOperation function is marked as inline. It takes two integers, a and b, and a lambda expression representing an operation to be performed on a and b. When performOperation is called, instead of generating a function call, the compiler directly replaces the code inside the function with the code from the lambda expression.
So, in the main function, the call to performOperation(5, 3) will be replaced with the actual code 5 + 3. This eliminates the overhead of creating an anonymous class and improves performance.
BTW, How inlining works actually?
When you declare a function as inline in Kotlin, its body is substituted directly into the places where the function is called, instead of being invoked as a separate function. This substitution process is known as inlining.
Let’s take a look at an example to understand it more:
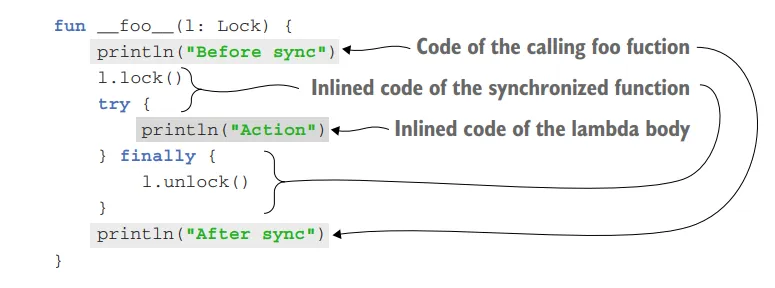
In this example, the synchronized function is declared as inline. It takes a Lock object and a lambda action as parameters. The function locks the Lock object, executes the provided action lambda, and then releases the lock.
When you use the synchronized function, the code generated for every call to it is similar to a synchronized statement in Java.
In this case, the lambda expression passed to synchronized is substituted directly into the code of the calling function. The bytecode generated from the lambda becomes part of the definition of the calling function and is not wrapped in an anonymous class implementing a function interface.
Not inlined Case (passing lambda as a parameter)
It’s worth noting that if you call an inline function and pass a parameter of a function type from a variable, rather than a lambda directly, the body of the inline function is not inlined.
Here’s an example:
Kotlin
classLockOwner(val lock: Lock) {funrunUnderLock(body: () -> Unit) {synchronized(lock, body) // A variable of a function type is passed as an argument, not a lambda. }}
In this case, the lambda’s code is not available at the site where the inline function is called, so it cannot be inlined. The body of the runUnderLock function is not inlined because there’s no lambda at the invocation. Only the body of the synchronized function is inlined; the lambda is called as usual. The runUnderLock function will be compiled to bytecode similar to the following function:
Kotlin
classLockOwner(val lock: Lock) {fun__runUnderLock__(body: () -> Unit) { // This function is similar to the bytecode the real runUnderLock is compiled to lock.lock()try {body() // The body isn’t inlined, because there’s no lambda at the invocation. } finally { lock.unlock() } }}
Here, the body of the runUnderLock function cannot be inlined because the lambda is passed as a parameter from a variable (body) rather than directly providing a lambda expression.
Suppose when you pass a lambda as a parameter directly, like this:
Kotlin
lockOwner.runUnderLock {// code block A}
The body of the inline function runUnderLock can be inlined, as the compiler knows the exact code to replace at the call site.
However, when you pass a lambda from a variable, like this:
Kotlin
val myLambda = {// code block A}lockOwner.runUnderLock(myLambda)
The body of the inline function cannot be inlined because the compiler doesn’t have access to the code inside the lambda (myLambda) at the call site. It would require the compiler to know the contents of the lambda in order to inline it.
In such cases, the function call behaves like a regular function call, and the body of the function is not copied to the call site. Instead, the lambda is passed as an argument to the function and executed within the function’s context.
So, suppose even though the runUnderLock function is marked as inline, the body of the function won’t be inlined because the lambda is passed as a parameter from a variable.
What about multiple inlining?
If you have two uses of an inline function in different locations with different lambdas, each call site will be inlined independently. The code of the inline function will be copied to both locations where you use it, with different lambdas substituted into it.
If you have multiple calls to the inline function with different lambdas, like this:
Each call site will be inlined independently. The code of the inline function will be copied to both locations where you use it, with different lambdas substituted into it. This allows the compiler to inline the code at each call site separately.
Restrictions on inline functions
When a function is declared as inline in Kotlin, the body of the lambda expression passed as an argument is substituted directly into the resulting code. However, this substitution imposes certain restrictions on how the corresponding parameter can be used in the function body.
If the parameter is called directly within the function body, the code can be easily inlined. But if the parameter is stored for later use, the code of the lambda expression cannot be inlined because there must be an object that contains this code.
In general, the parameter can be inlined if it’s called directly or passed as an argument to another inline function. If it’s used in a way that prevents inlining, such as storing it for later use, the compiler will prohibit the inlining and show an error message stating “Illegal usage of inline-parameter.”
Let’s consider an example with the Sequence.map function:
Kotlin
fun <T, R> Sequence<T>.map(transform: (T) -> R): Sequence<R> {returnTransformingSequence(this, transform)}
The map function doesn’t call the transform function directly. Instead, it passes the transform function as a constructor parameter to a class (TransformingSequence) that stores it in a property. To support this, the lambda passed as the transform argument needs to be compiled into the standard non-inline representation, which is an anonymous class implementing a function interface.
Why Use Inline Functions in Kotlin?
Inline functions are particularly useful in scenarios where:
Performance Optimization: Reduces function call overhead, making execution faster.
Avoiding Anonymous Object Allocations: Reduces memory allocations by avoiding extra objects for lambdas.
When Not to Use Inline Functions
Although inline functions in Kotlin are beneficial, overusing them can lead to code bloat (increased code size). Here are some situations where you should avoid using inline functions:
Large Function Bodies: If the function body is large, inlining it multiple times will increase the APK size.
Non-Performance Critical Code: For functions that don’t need optimization, inlining may be unnecessary.
Recursion: Recursive inline functions are not allowed in Kotlin since they would cause infinite expansion.
Performance Benefits of Inline Functions
The key benefits of inline functions in Kotlin include:
Reduces function call overhead – No need for extra method calls.
Eliminates unnecessary object creation – No wrapper objects for lambda functions.
Improves performance for high-order functions – Especially beneficial when passing multiple lambdas.
Inline functions in Kotlin are a powerful tool for improving performance, especially when working with higher-order functions and lambda expressions. By eliminating function call overhead and avoiding unnecessary object creation, they help make Kotlin code more efficient.
However, inline functions should be used carefully. Overuse can lead to increased bytecode size, making your application slower rather than faster. The key is to strike a balance—use them where they add value but avoid excessive inlining.